Home
>
Blog
>
>
How De-Duplication Should Work Before Indexing Medical Records
- De-duplication should happen after the records are inventoried and Bates numbered, but before indexing, so the index and page counts are built on a clean set.
- Do not blindly delete duplicates. In a legal production, mark and set aside rather than destroy, so the record can always explain itself.
- Distinguish exact duplicates from near-duplicates: two copies of the same page are safe to consolidate; two versions that differ by an annotation are two facts.
- Keep every retained record traceable to its Bates page, so a consolidated set stays verifiable and defensible.
- Automated tools can flag likely duplicates fast, but a human should confirm before anything is removed from view.
De-duplication is one of those steps everyone agrees matters and almost no one sequences correctly. Done at the right moment, it makes a medical record review faster and cheaper to index. Done at the wrong moment, or done too aggressively, it can quietly damage the very file it was supposed to clean.
De-duplication should happen after the records are accounted for and Bates numbered, but before the file is indexed, and it should mark duplicates rather than blindly delete them. Get that sequence and that restraint right, and the index, the page count, and every review built on the file all hold up. Get it wrong, and you have a tidy-looking set that cannot explain itself.
Let me walk through what de-duplication actually is, why the order matters so much, and how to do it without introducing the problems that careless duplicate removal creates.
What de-duplication is, and what it is not
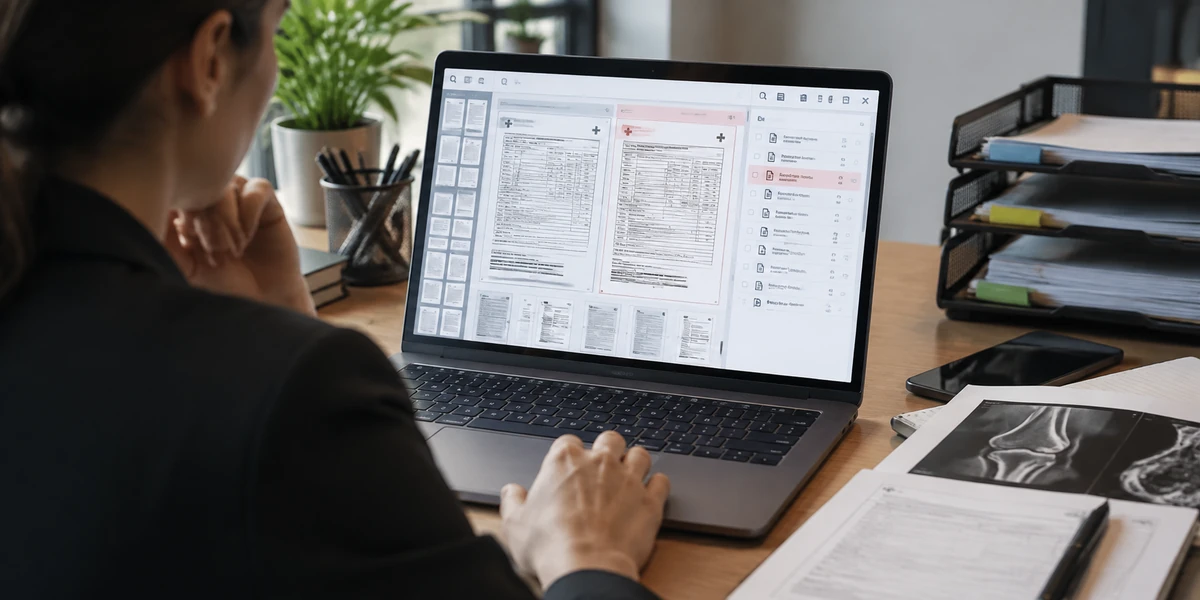
De-duplication is the process of identifying redundant copies of the same record in a production and consolidating them, so a reviewer is not reading, and paying for, the same page three times. In a typical medical production, the same operative report can arrive from the hospital, from the treating physician's file, and again in a payer's records, so a 2,000-page set might carry hundreds of pages that add nothing new.
What de-duplication is not is deletion for its own sake. Removing pages from a legal production is not a housekeeping decision; it is a decision with consequences for page counts, for what was actually served, and for the file's ability to defend itself later. That distinction is the whole reason the how and the when matter.
The cheapest page to review is the one you never review twice
Duplicate pages inflate review time and cost without adding a single new fact. In a large production, consolidating them before indexing is one of the few steps that makes a file both faster to work and cheaper to review, without changing what the records say.
Why duplicates appear, and why they are not all the same
Duplicates are not a sign of a sloppy production. They are the normal result of records arriving from many sources. The same hospital stay is documented in the hospital's chart, referenced in the treating physician's notes, copied into the payer's file, and produced again in response to a subpoena. Each source honestly includes its copy, and the copies pile up.
The important thing, and the thing careless de-duplication gets wrong, is that not every apparent duplicate is a true duplicate.
Exact duplicates
An exact duplicate is the same page, scan for scan: identical content, identical layout, no differences. Two copies of the same discharge summary from the same source are safe to consolidate down to one, with a note that a copy existed.
Near-duplicates
A near-duplicate looks the same at a glance and is not. It is the same base document with a handwritten annotation on one copy, a different fax stamp, a signature on one version and not the other, or a page that was updated between productions. These are two different facts, not one, and a tool or a reviewer that treats them as interchangeable can discard the only copy that carried the note that mattered. Telling exact duplicates from near-duplicates is where real de-duplication earns its keep.
Paying to review the same page three times?
Mark, do not blindly delete
The single biggest mistake in de-duplication is destroying pages. It feels efficient to simply delete every copy after the first, but in a legal file that creates two problems that surface at the worst time.
First, page counts and productions have to reconcile. If the file was served with a certain number of pages and your working set has quietly fewer, someone eventually asks why, and "we deleted the duplicates" is a weaker answer than "the duplicates are marked and set aside, here they are." Second, a duplicate that arrived from two different sources is itself a fact. The same report appearing in both the treating physician's file and the payer's file tells you something about what each party had and when. Delete one, and that signal is gone.
The defensible approach is to consolidate for review while preserving the record. Mark duplicates, set them aside in a clearly labeled section rather than the trash, and keep every page's Bates number intact so the working set and the full production can always be reconciled. The reviewer reads a clean file; the complete production still exists and can explain itself. Nothing is lost, and nothing is hidden.
In a legal file, a deleted duplicate is not a tidy file. It is a page you can no longer account for.
Where de-duplication belongs in the sequence
De-duplication is not a standalone task you run whenever. It sits in a specific place in the workflow, and the place is the point.
The order that works is this. First, account for every page and Bates number the entire production, so every page has a permanent address before anything is touched. Second, de-duplicate: identify exact duplicates, distinguish them from near-duplicates, and consolidate the exact ones while marking and preserving what is set aside. Only then, third, index the cleaned set, so the index and its page counts describe the file a reviewer will actually use.
The reason de-duplication comes before indexing is simple. If you index first and de-duplicate second, the index is immediately wrong: it points to pages that have moved, counts records that were copies, and has to be rebuilt. If you de-duplicate first, the index is built once, on a clean set, and every entry and page reference in it is accurate. And because de-duplication comes after Bates numbering, every consolidated record still traces to a real page in the original production.
Two things have to be true throughout: every retained record stays traceable to its Bates page, and every set-aside duplicate remains recoverable. Those two rules are what keep a de-duplicated file both clean and defensible.
How de-duplication should be done
After Bates
Numbered first
Every page gets a permanent address before any duplicate is touched.
Before indexing
Clean set, built once
The index describes the file a reviewer actually uses, not one that shifts later.
Marked
Preserved, not deleted
Duplicates are set aside and recoverable, so the production always reconciles.
Where AI helps, and where a human has to look
Automated tools have made the first pass of de-duplication genuinely fast. Software can compare pages across an entire production and flag likely duplicates in minutes, using text and image matching that no person could do at that speed. On a large file, that first pass is worth having.
The limit is the near-duplicate. A matching algorithm keys on similarity, and two pages that are ninety-nine percent identical will be flagged as duplicates even when the one-percent difference, a handwritten note, an added signature, a corrected value, is the whole point. This is exactly where an automated tool will confidently discard the copy that mattered. So the reliable setup pairs the speed of automated flagging with a human who confirms before anything is removed from view. The tool proposes; a reviewer decides.
That is the through-line of doing de-duplication well. It runs after the pages are numbered and before the file is indexed, it consolidates exact duplicates while preserving near-duplicates and everything it sets aside, and it keeps a human in the loop for the judgment calls. Do it that way and you get a file that is faster to review, cheaper to index, and still able to account for every page it started with.
A legal nurse consultant organizes the records, consolidate and flag duplicates, and keep the set traceable and complete. They do not diagnose, decide causation, or reach a legal conclusion. Those calls stay with the attorney and the physician, working from a clean, defensible file.
Source Credit : All metrics derived from LezDo TechMed’s internal project data.
Janu Padmaprasad
Janu Padmaprasad is a certified Legal Nurse Consultant with seven years of experience in the medical-legal ecosystem. She understands the operational and evidentiary challenges faced by injury attorneys, medical evaluators, life care planners, and insurance professionals. By combining her research insights with expertise in medical chronology preparation, she writes solution-driven articles on medical data analysis that help medical-legal experts strengthen case outcomes and enhance their business operations.